|
Zhihao Yang yangzhihao25 [at] mails.ucas.ac.cn
Hello! Welcome to my homepage. I enjoy basketball and rock climbing. My favorite team is the Golden State Warriors. I am a huge fan of Stephen Curry! |

|
Publications |
First Author* equal contribution; † corresponding author |
|
|
Scaling in Games: Continued Pre-Training for Embodied Agents in Diverse Virtual Worlds
arXiv, 2026 [paper] [project page] [github] [models] [demo] How data, world diversity, and model size scale continued pre-training for embodied agents. |
|
|
Video-Arena: A Scalable Agentic Video Benchmark for Spatiotemporal Capability
arXiv, 2026 [paper] [project page] [github] [dataset] [demo] A video benchmark for perceiving events, reading state updates, and tracking an evolving world. |
|
|
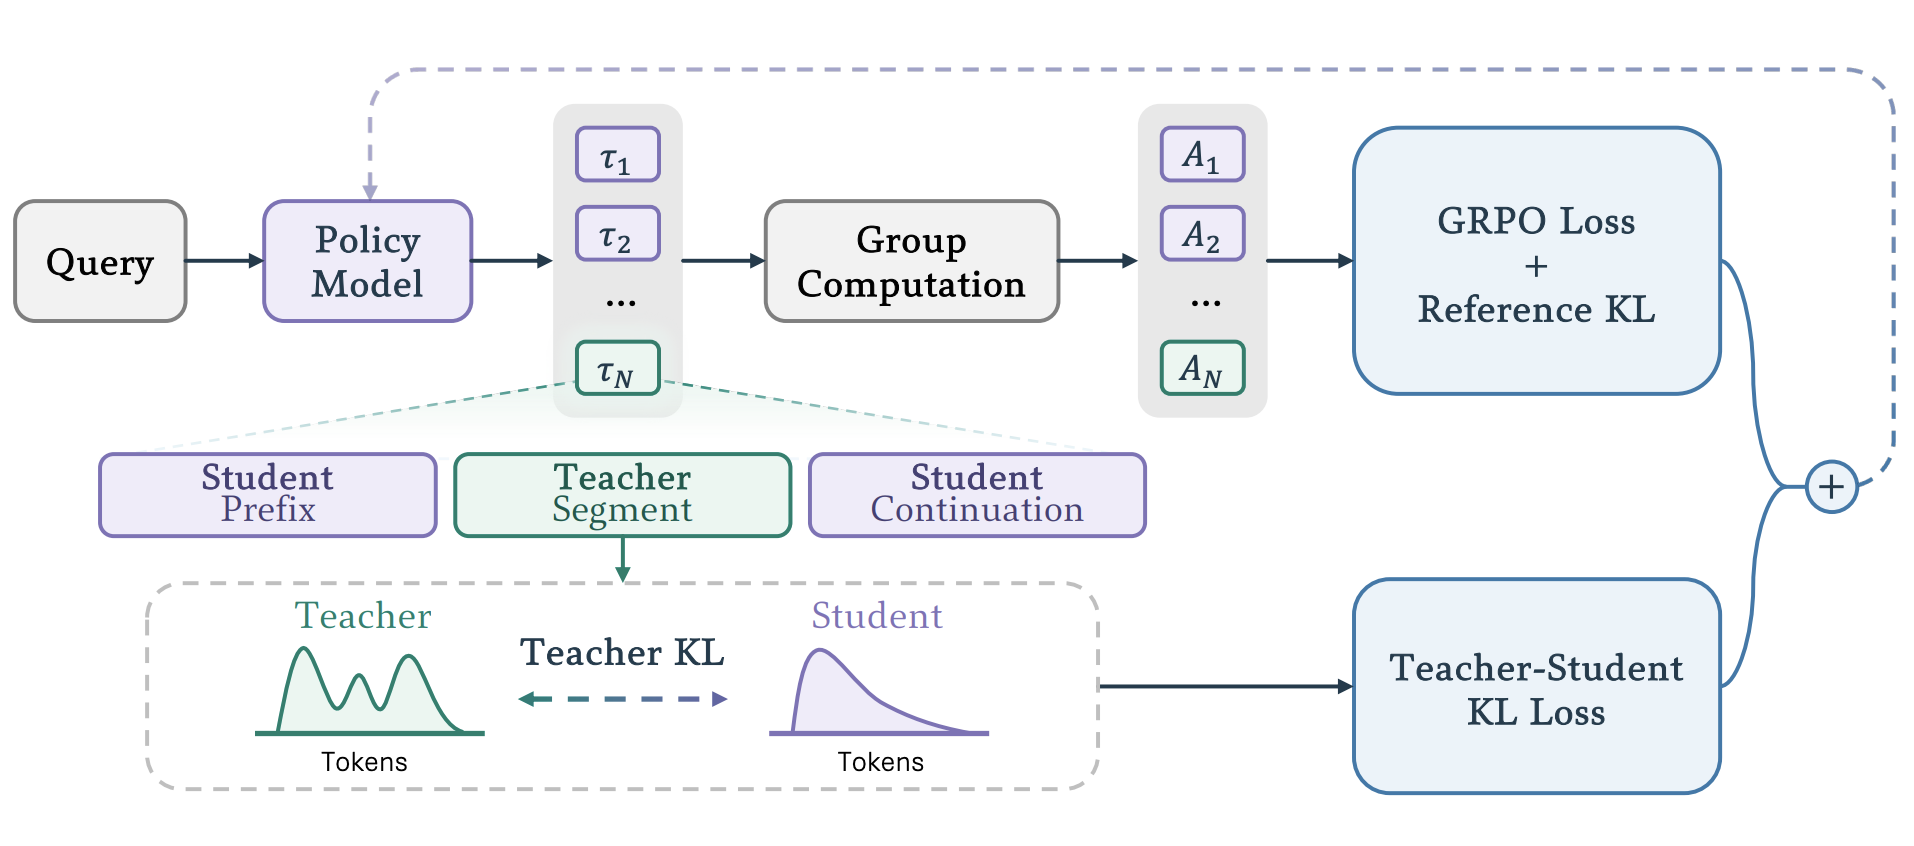
PIVOT: Progressive Intervention via Online Teacher Correction
arXiv, 2026 A teacher-assisted RLVR method that inserts teacher corrections into student rollouts and applies token-level KL supervision, nearly doubling mean avg@8 on hard logic games. |
|
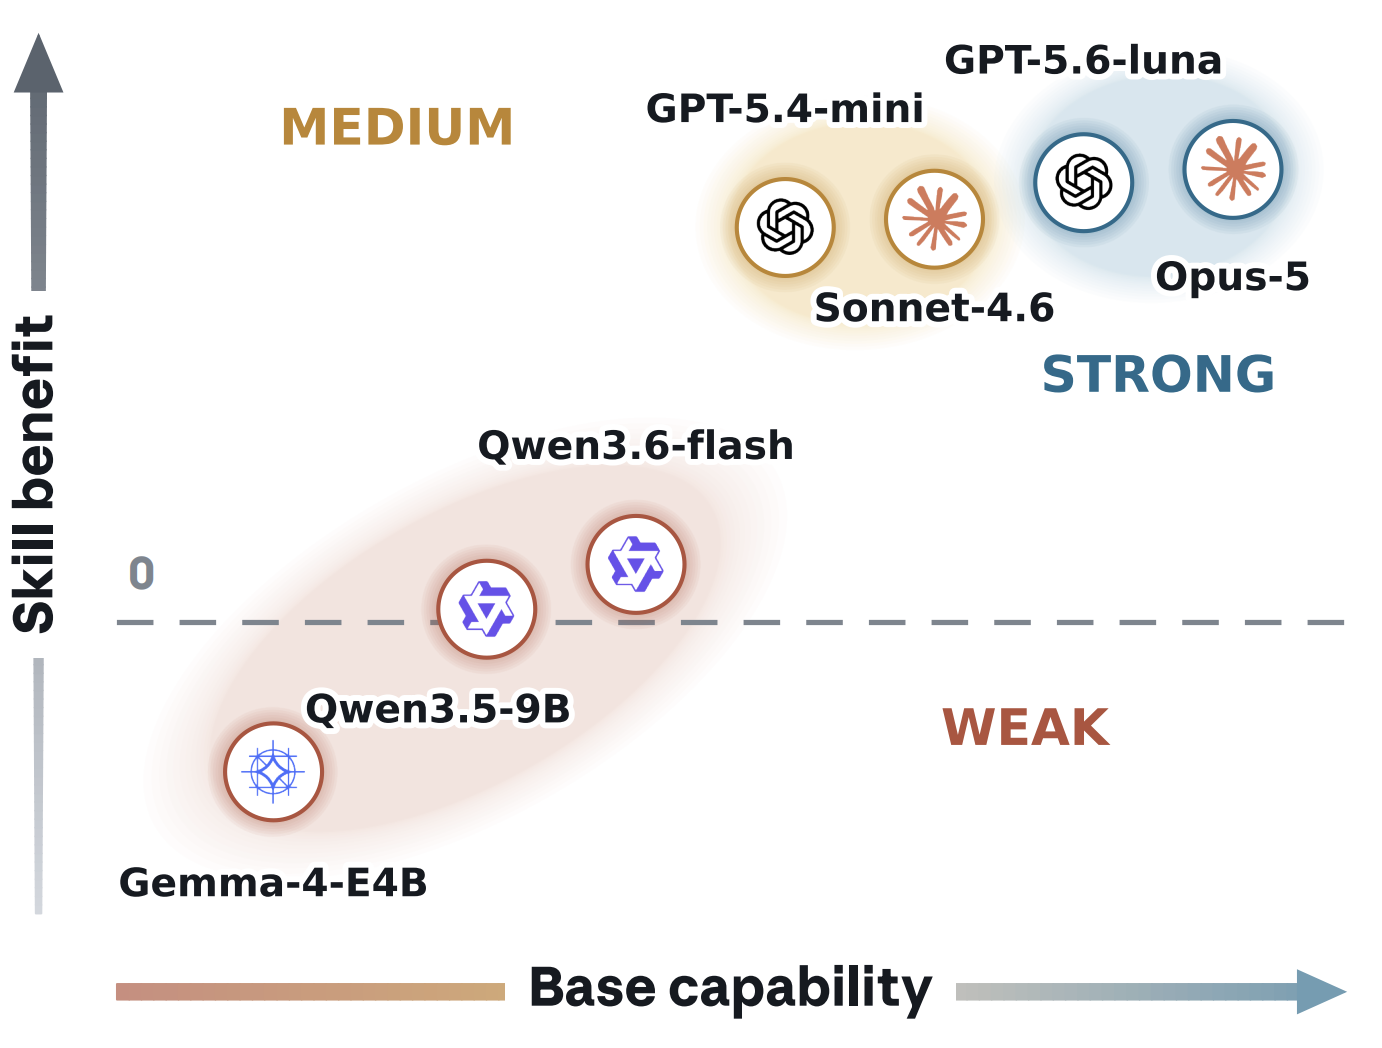
Evolving to Match Capabilities: Improving Harness Self-Evolution via Skill Adaptation
arXiv, 2026 [paper] [project page] [github] [X] A meta-skill that adapts harness guidance to the executor's capability, so self-evolution helps both weak and strong agents without updating model parameters. |
|
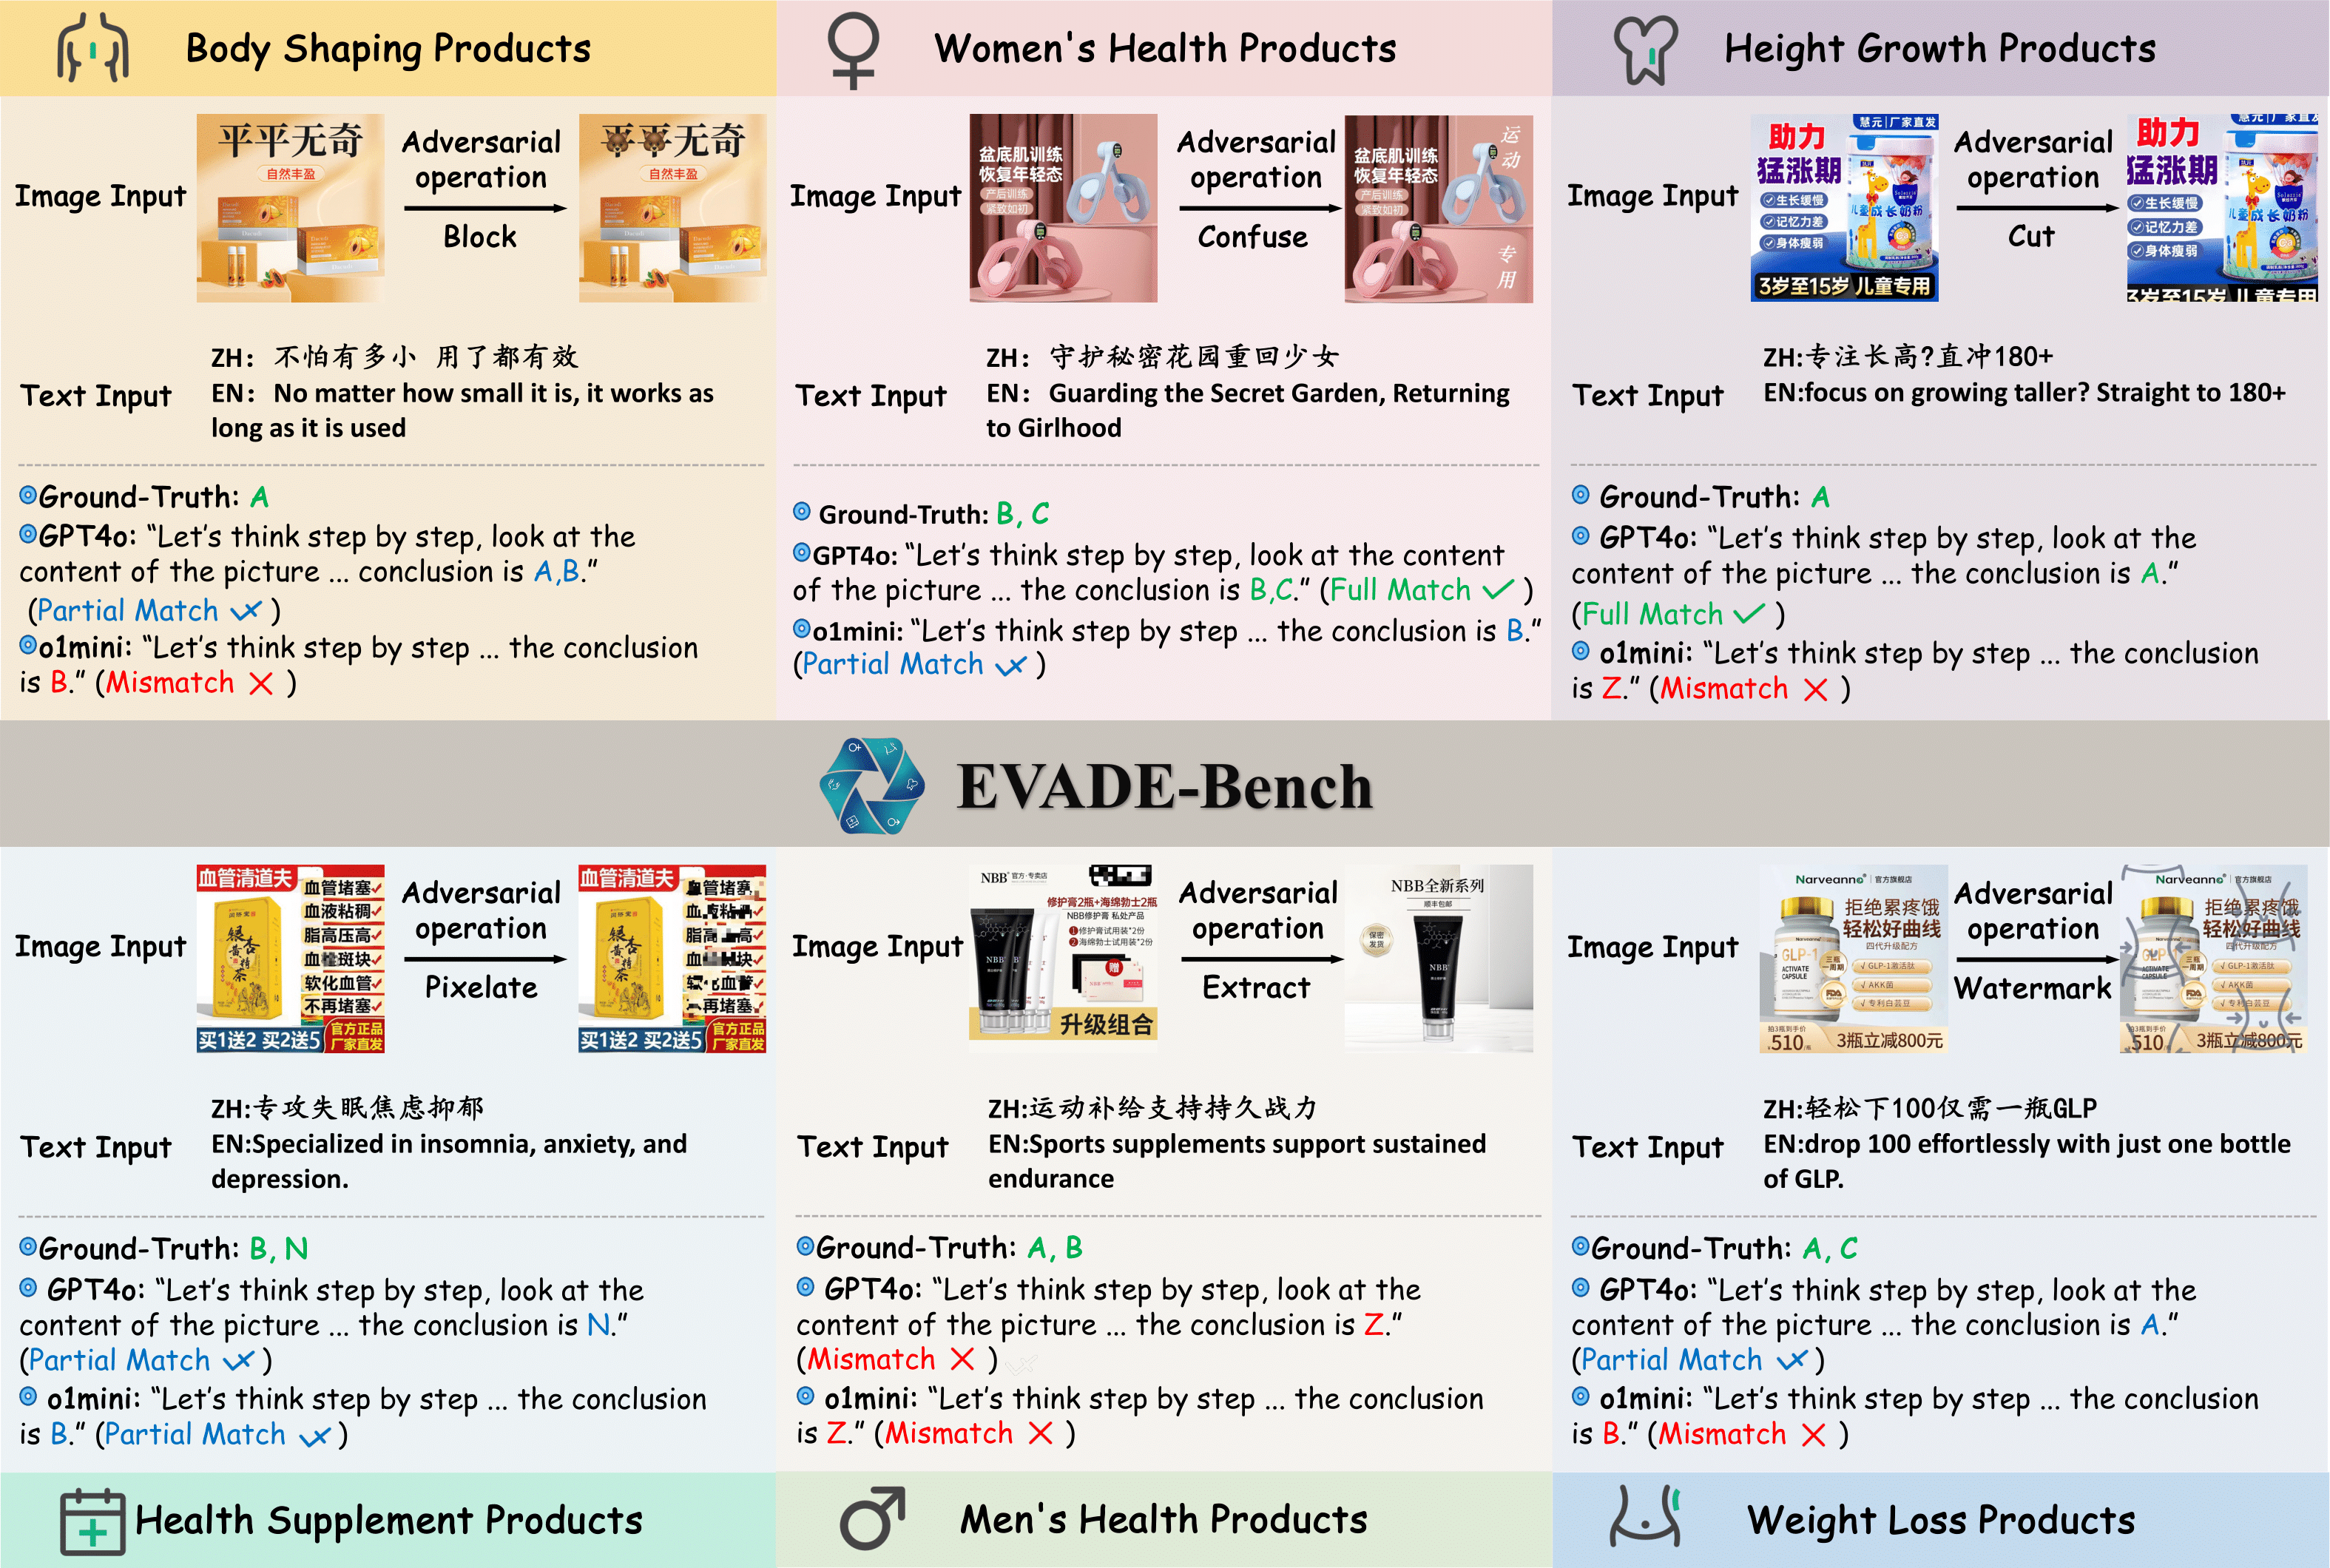
Evade: Multimodal benchmark for evasive content detection in e-commerce applications
SIGIR, 2026 (CCF-A) [project page] [arXiv] EVADE-Bench introduces a multimodal benchmark to evaluate evasive content detection and provides a strong foundation for developing more robust detection systems. |
|
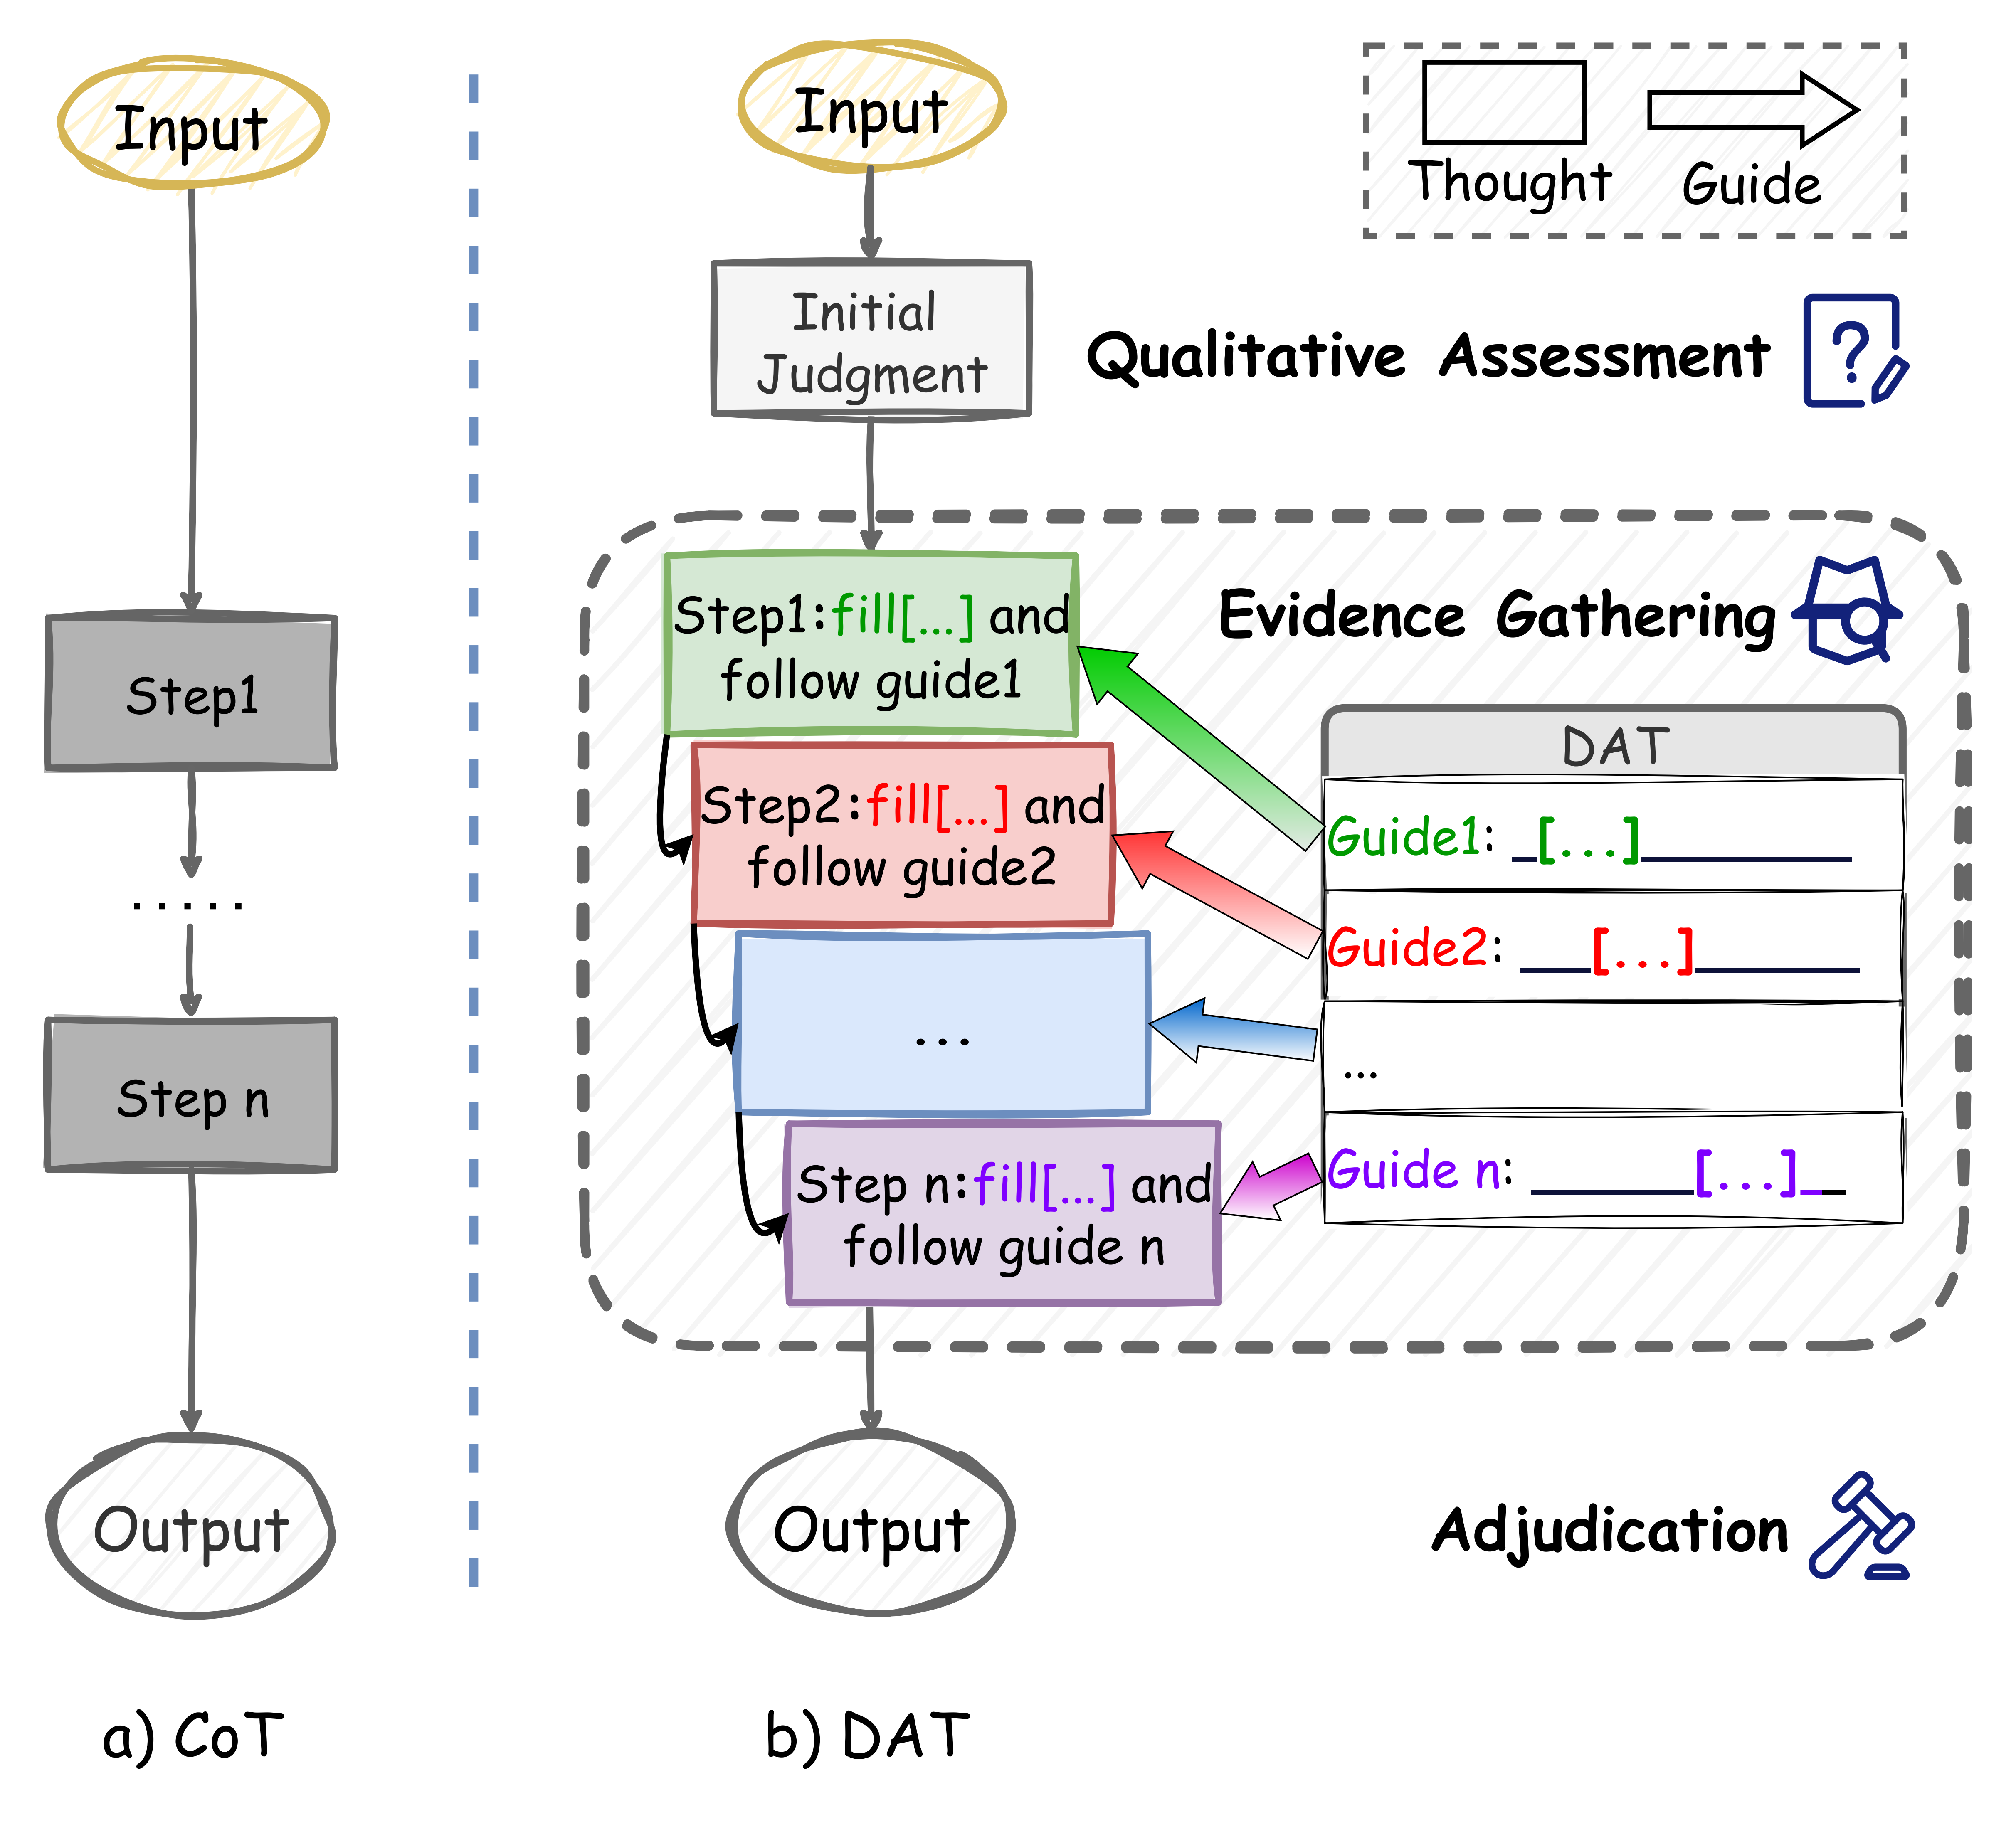
Structuring Reasoning for Complex Rules Beyond Flat Representations
arXiv, 2025 [arXiv] An approach which equips LLMs with a structured template to methodically gather and verify evidence within complex rule systems, drastically improving reasoning fidelity. |
Co-authored Papers |
|
|
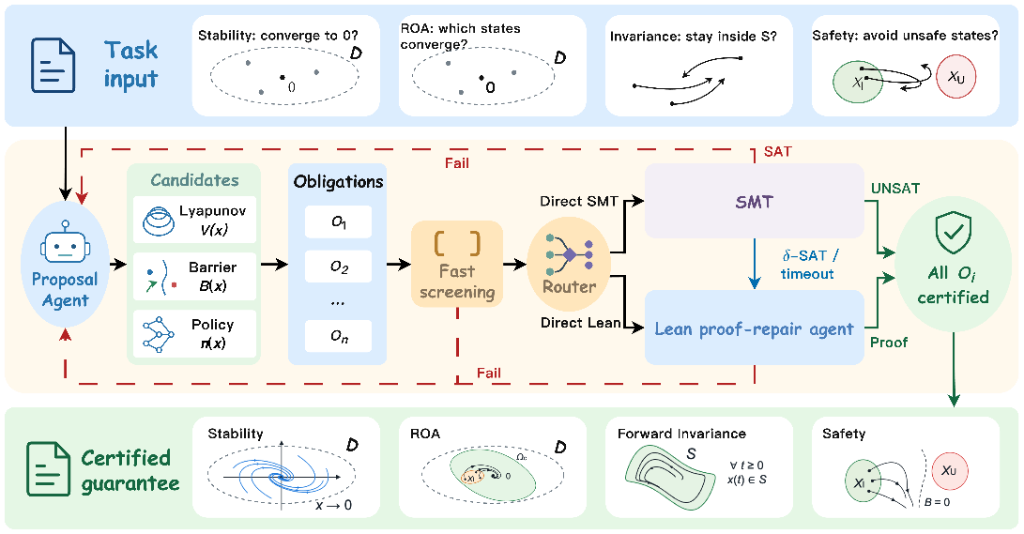
LLM2Cert: LLM Synthesis of Certificates with SMT/Lean Verification
arXiv, 2026 [paper] [project page] [github] [dataset] [X] An agent framework that synthesizes Lyapunov and barrier certificates for dynamical systems and verifies them with SMT and Lean, without accepting solver relaxations. |
|
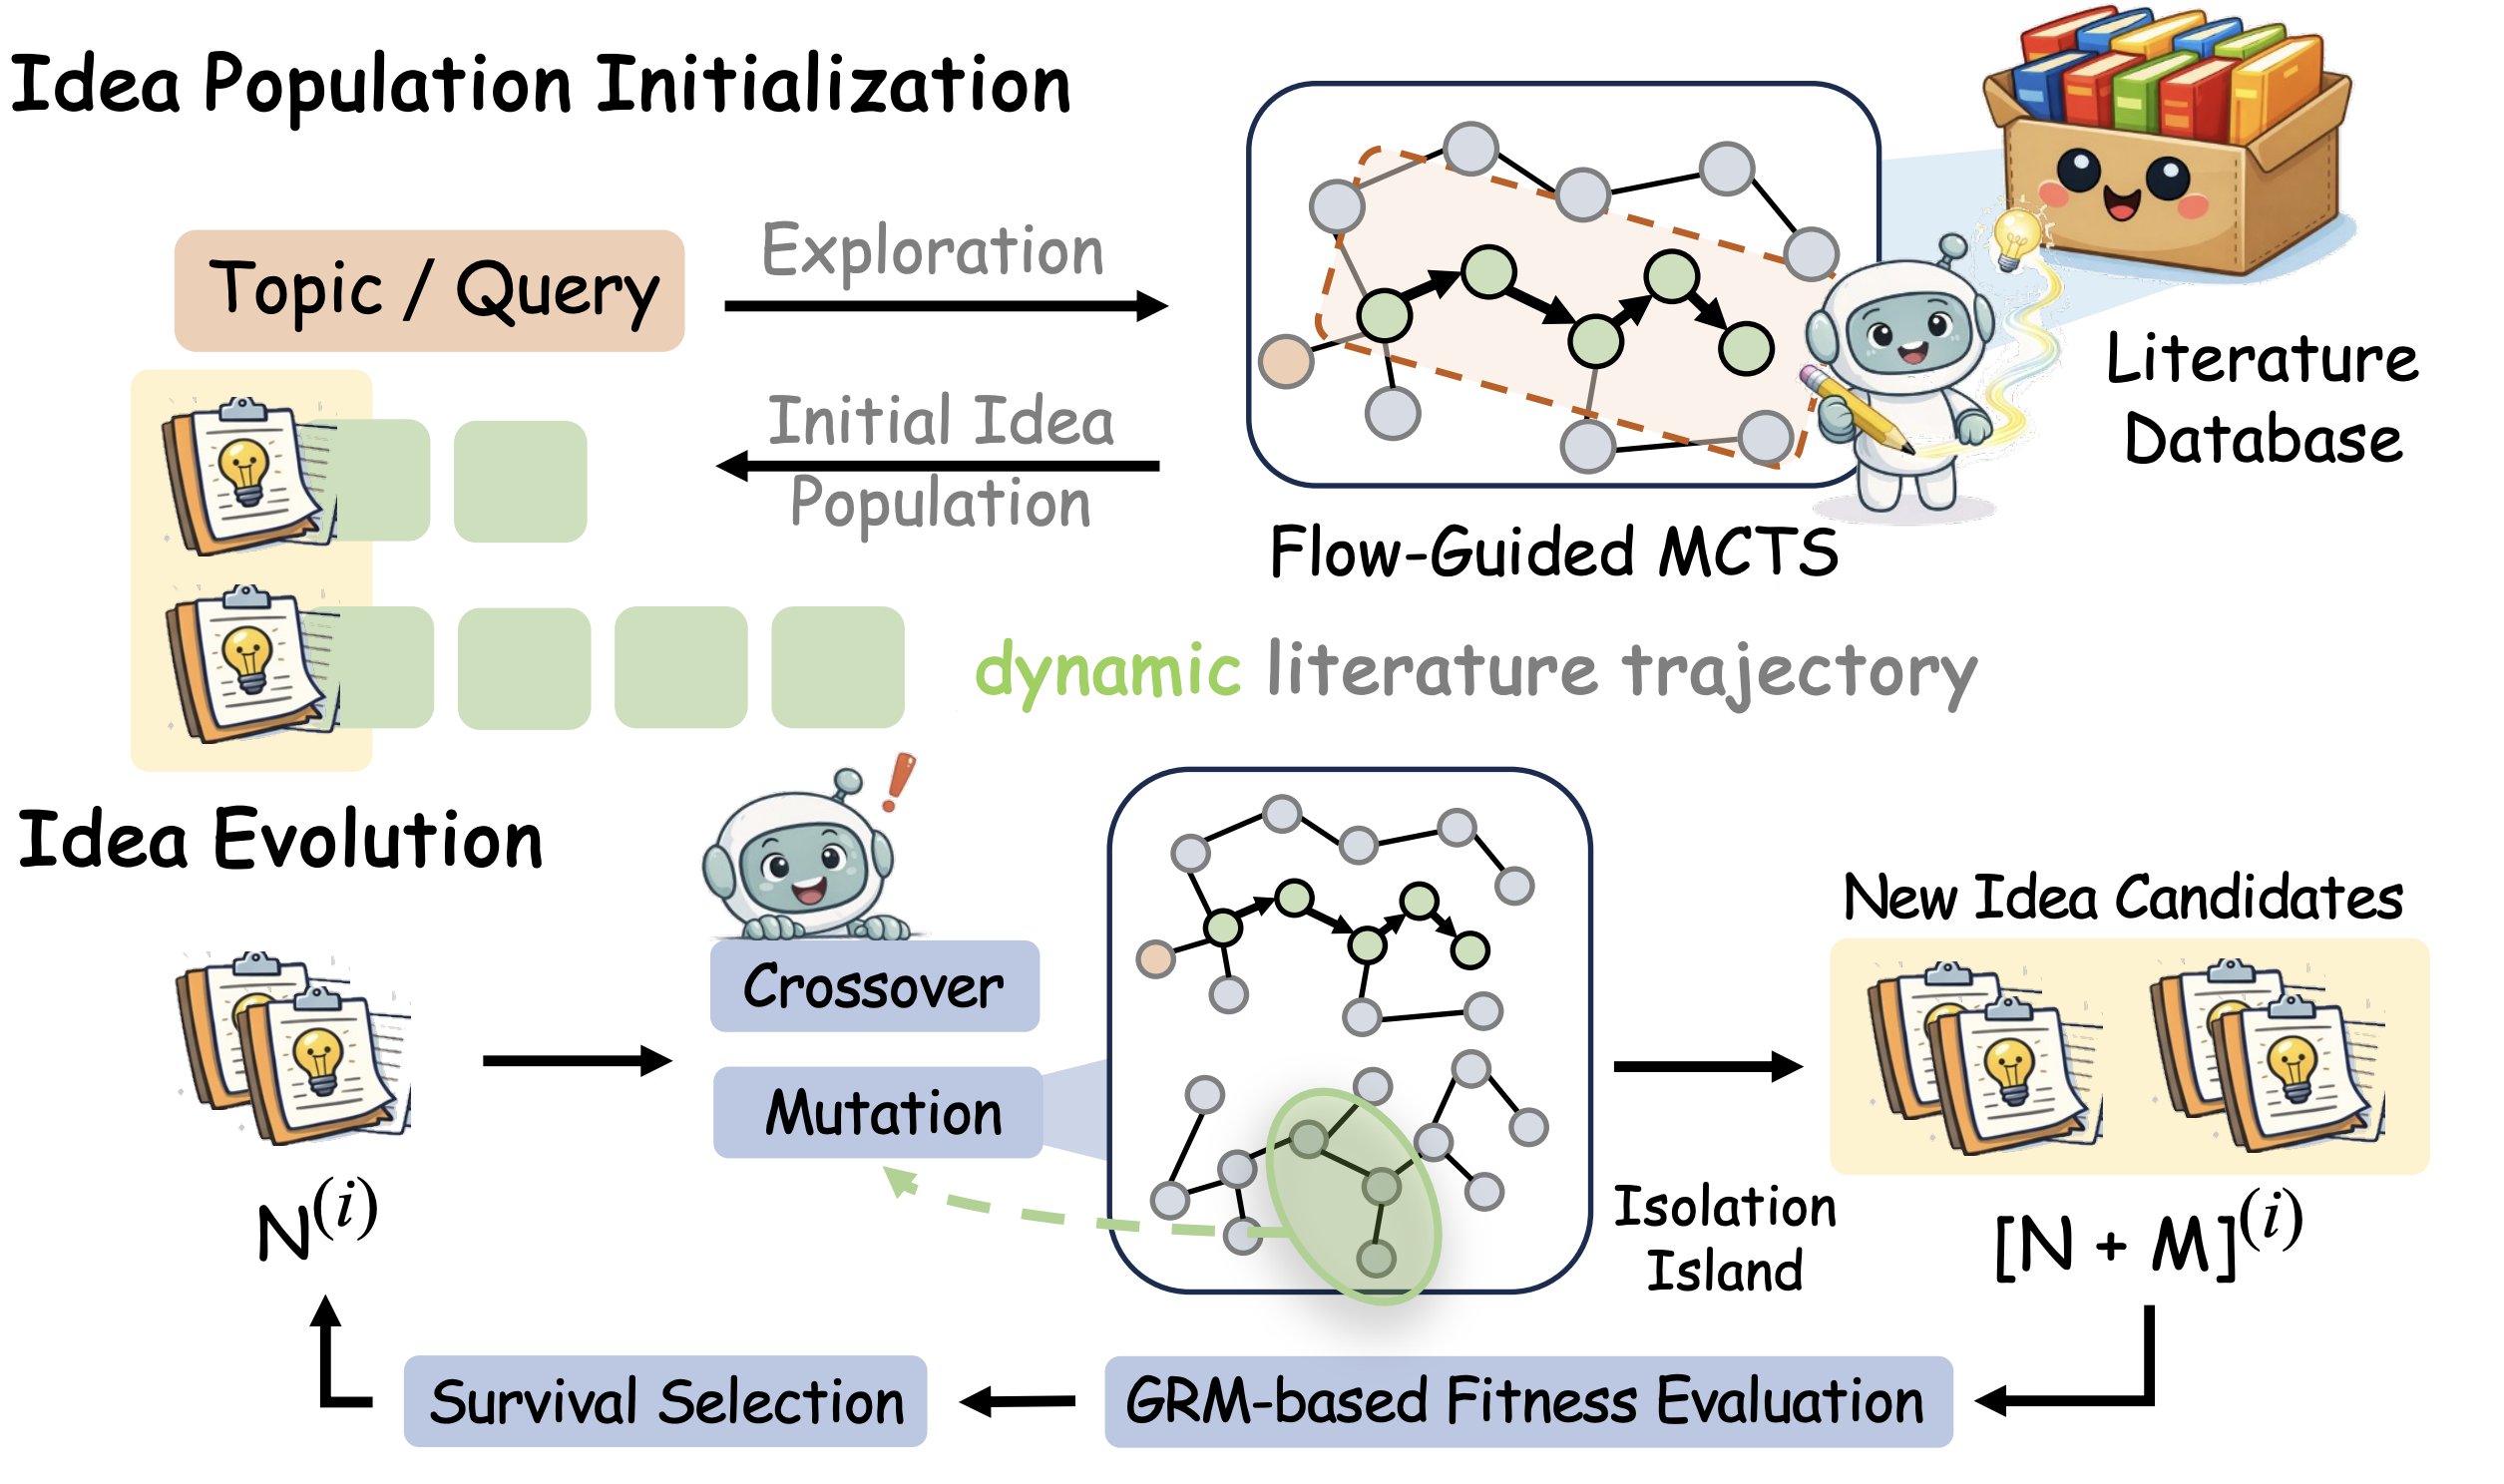
FlowPIE: Test-Time Scientific Idea Evolution with Flow-Guided Literature Exploration
arXiv, 2026 [paper] [project page] [github] [data] FlowPIE tightly couples literature retrieval with idea generation through flow-guided search and test-time evolution, producing research ideas that are more novel, diverse, and feasible than strong LLM- and agent-based baselines. |
|
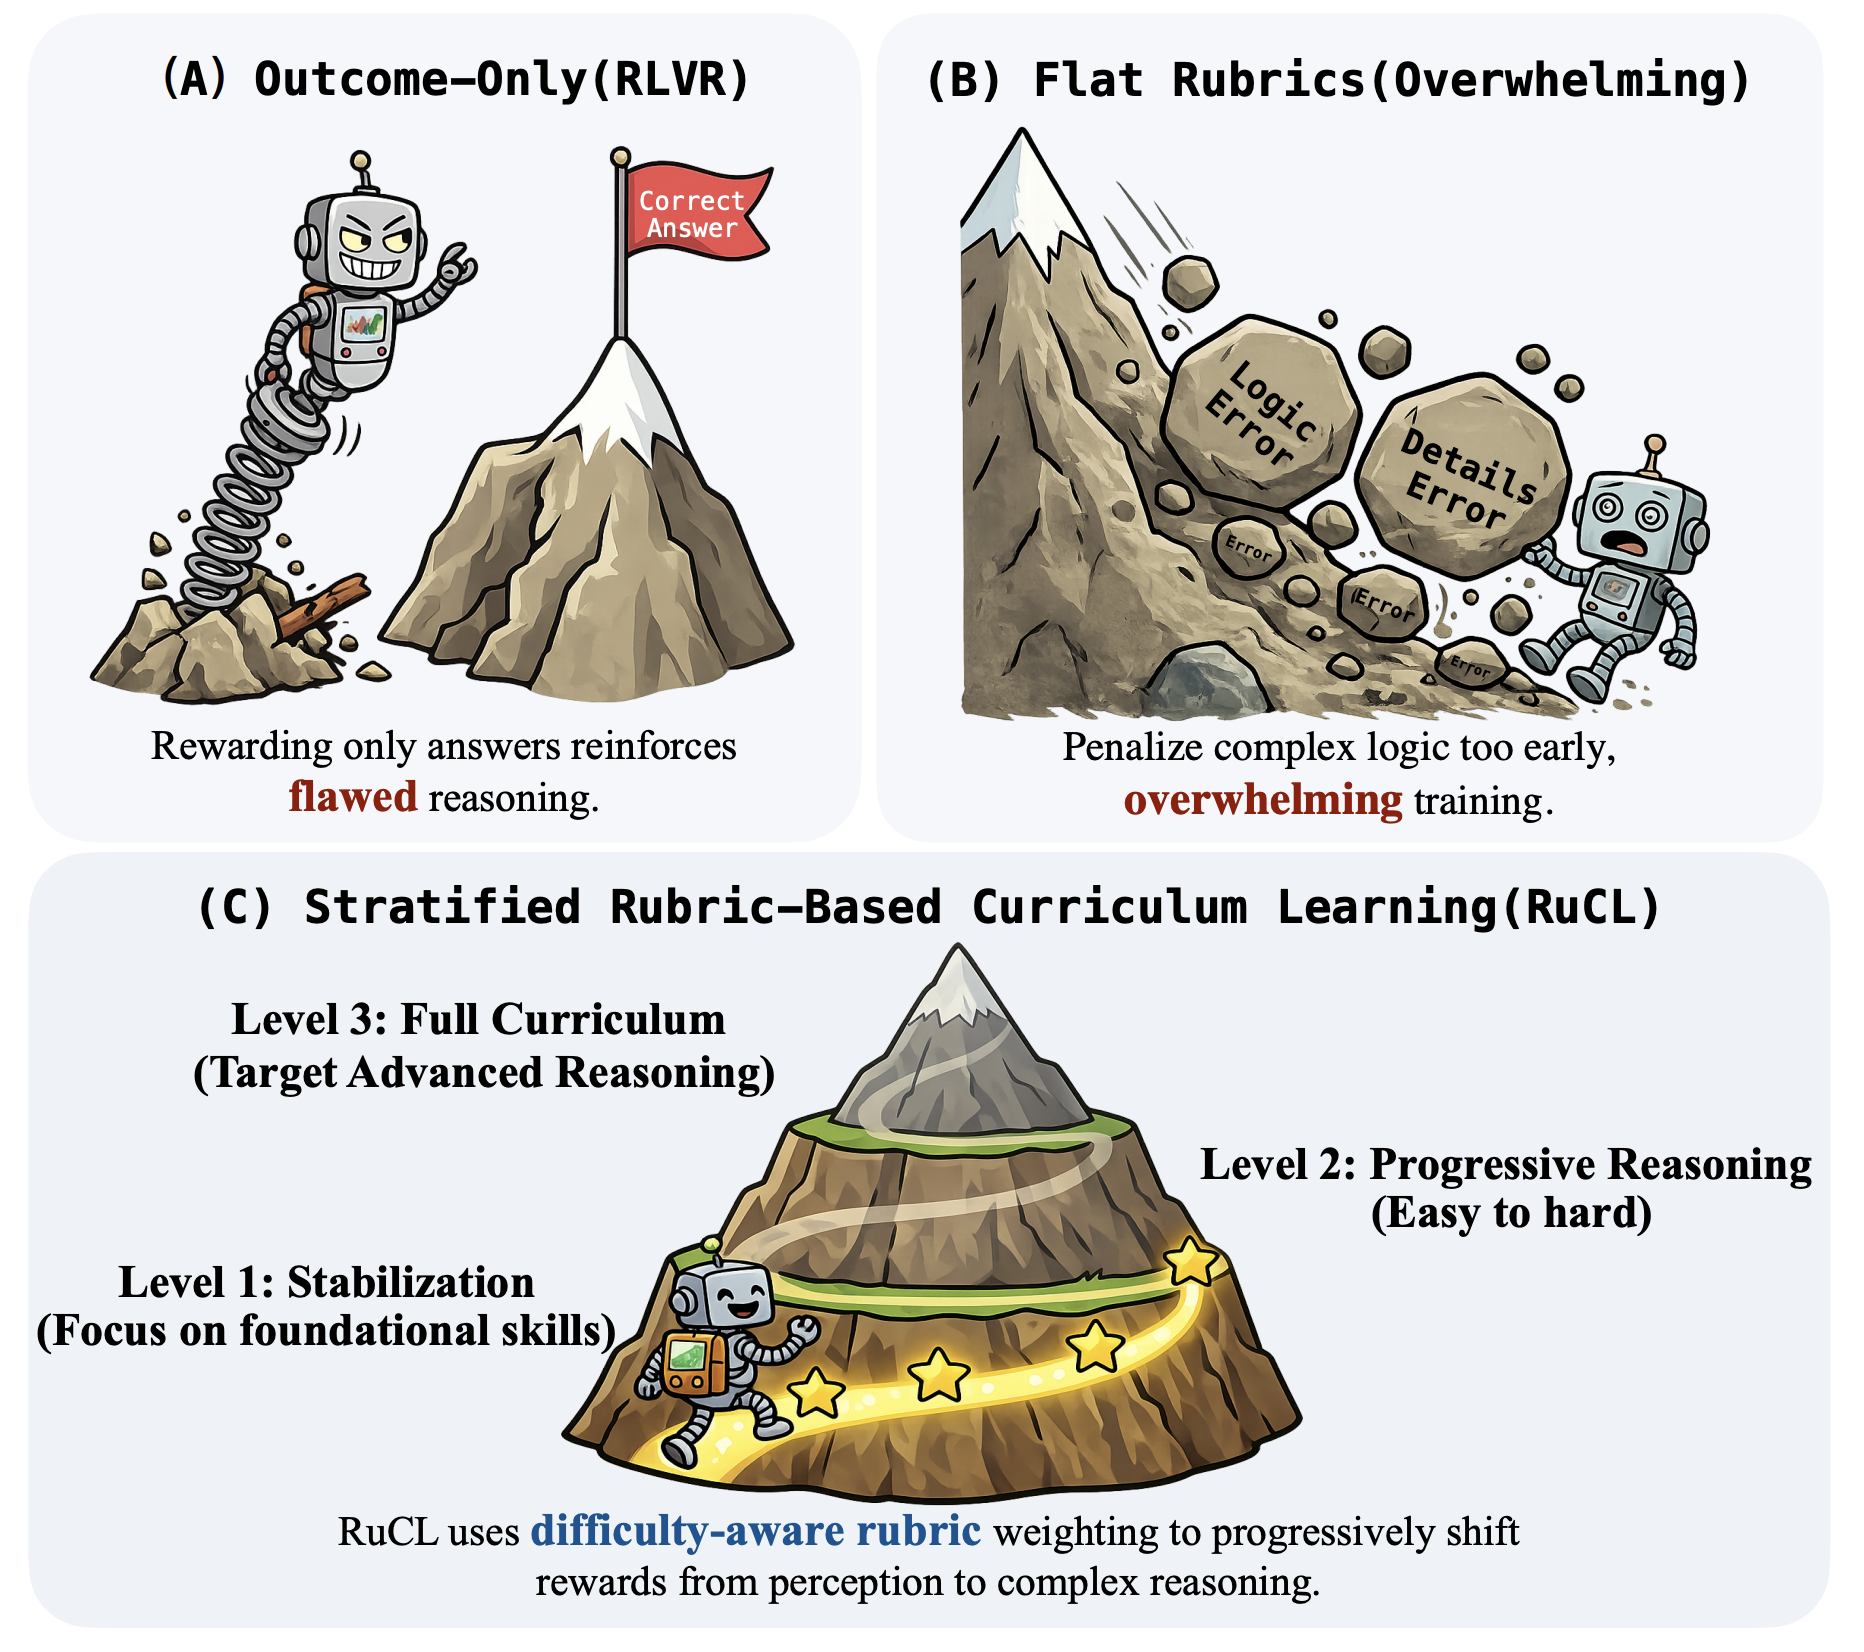
RuCL: Stratified Rubric-Based Curriculum Learning for Multimodal Large Language Model Reasoning
ICML, 2026 (CCF-A) [arXiv] RuCL reframes curriculum learning around reward design by stratifying rubrics according to model competence, then dynamically reweighting them to progressively improve multimodal reasoning from perception to higher-order logic. |
Working Experience |
|
|